01
A report for leadership
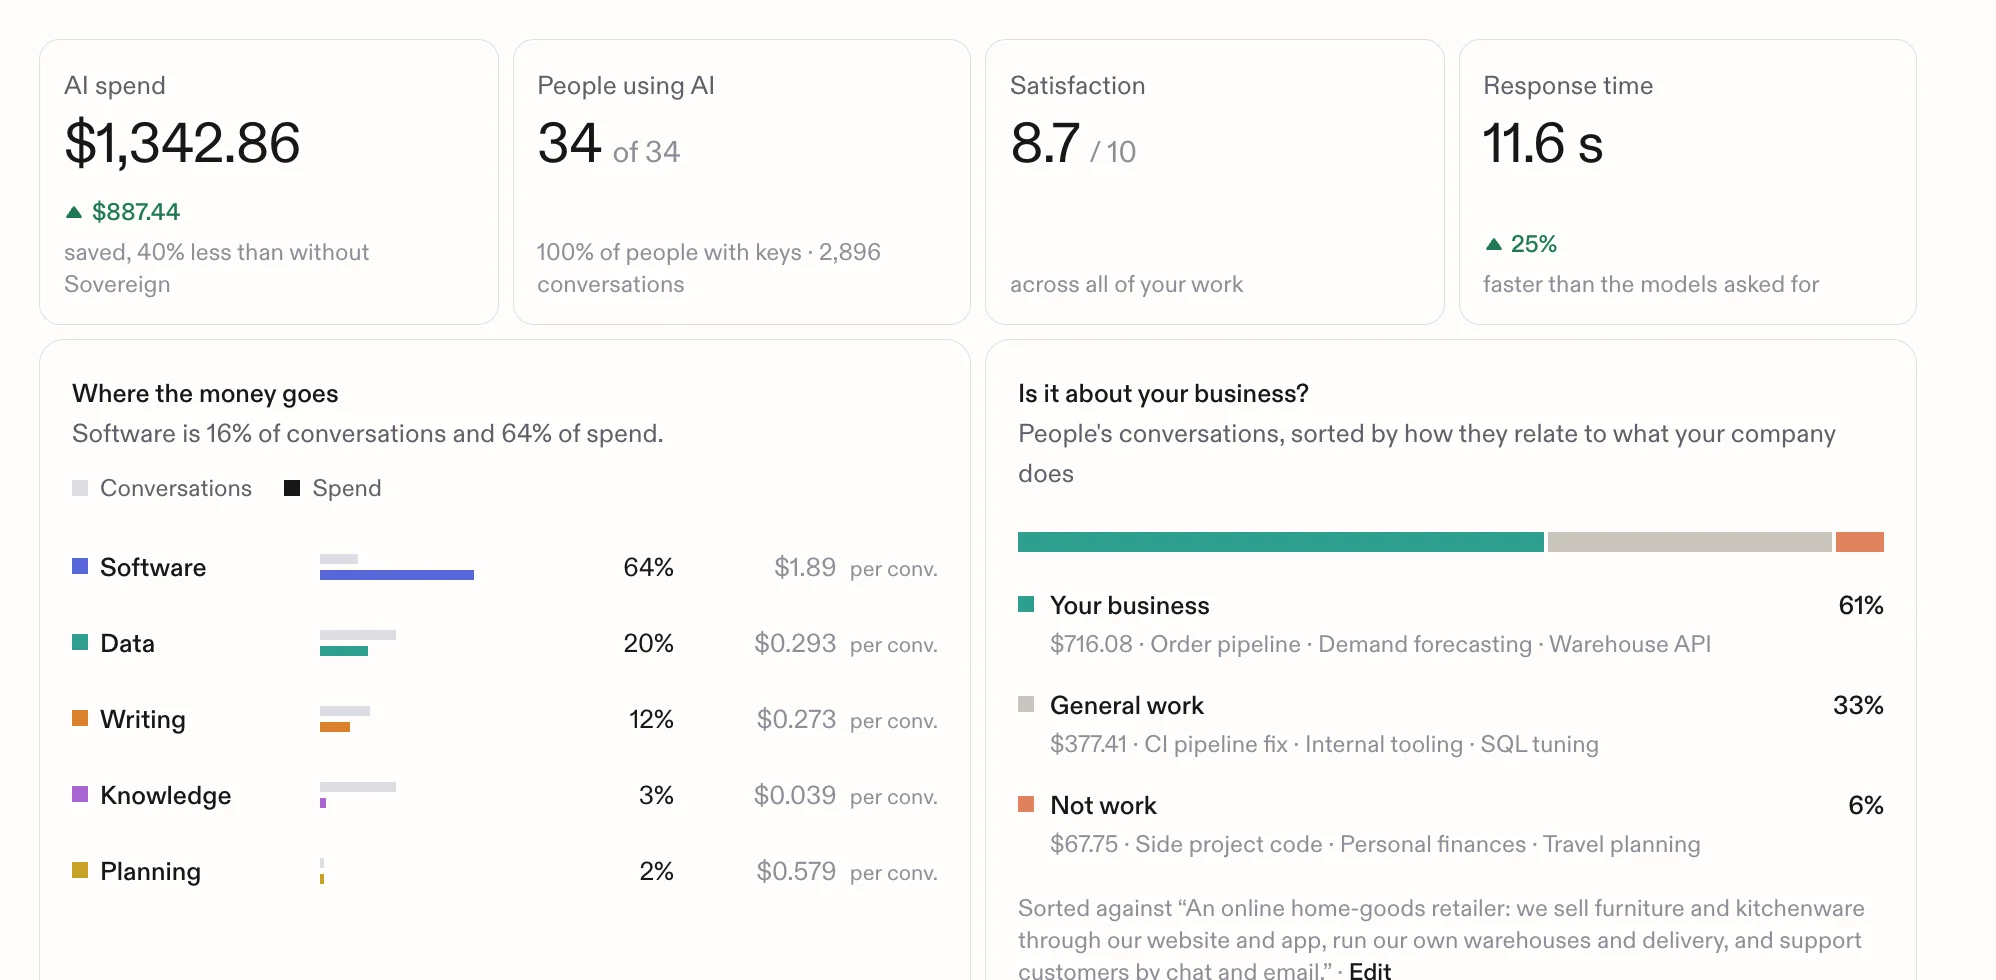
The month on one page: where AI money goes, how much of the work is about your business, and which teams get the most from it, each compared fairly on the same kinds of work. Save it as a PDF and send it.
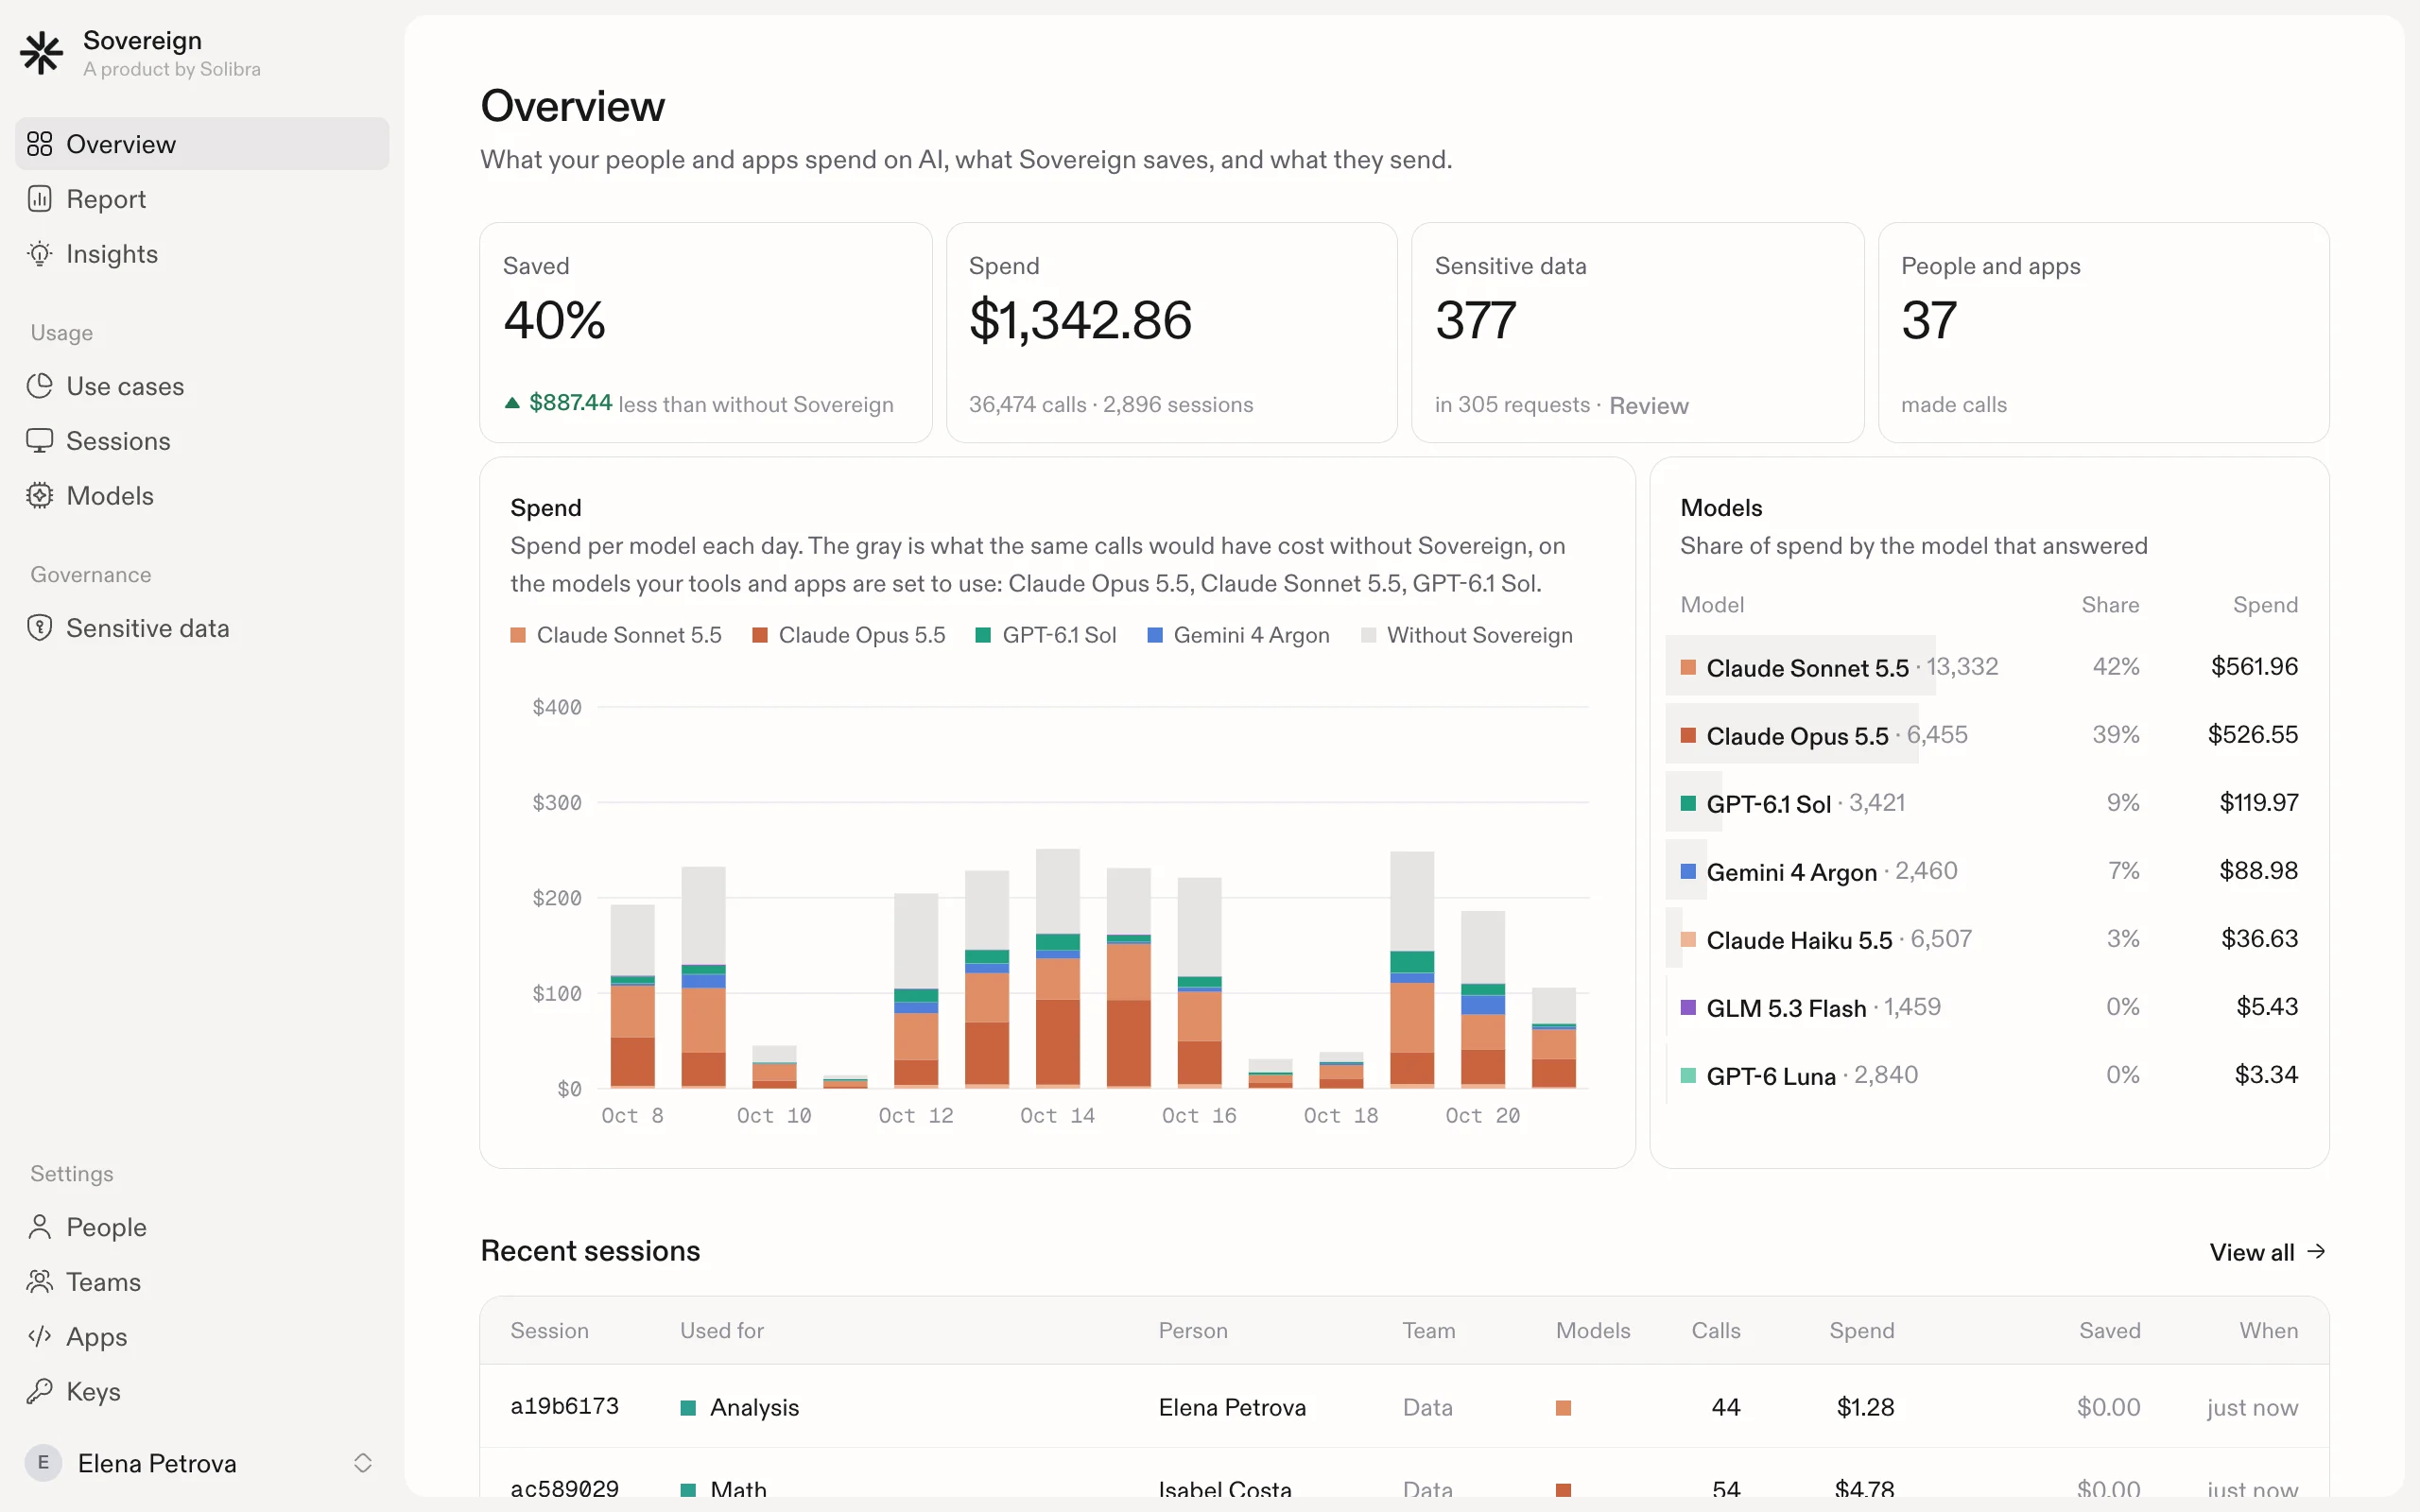
Sovereign is one gateway for your people, coding agents and apps. Each request goes to the model that does the work as well for less, so AI gets cheaper and faster, and leadership sees what it cost, what it saved and what it was for.
Route across
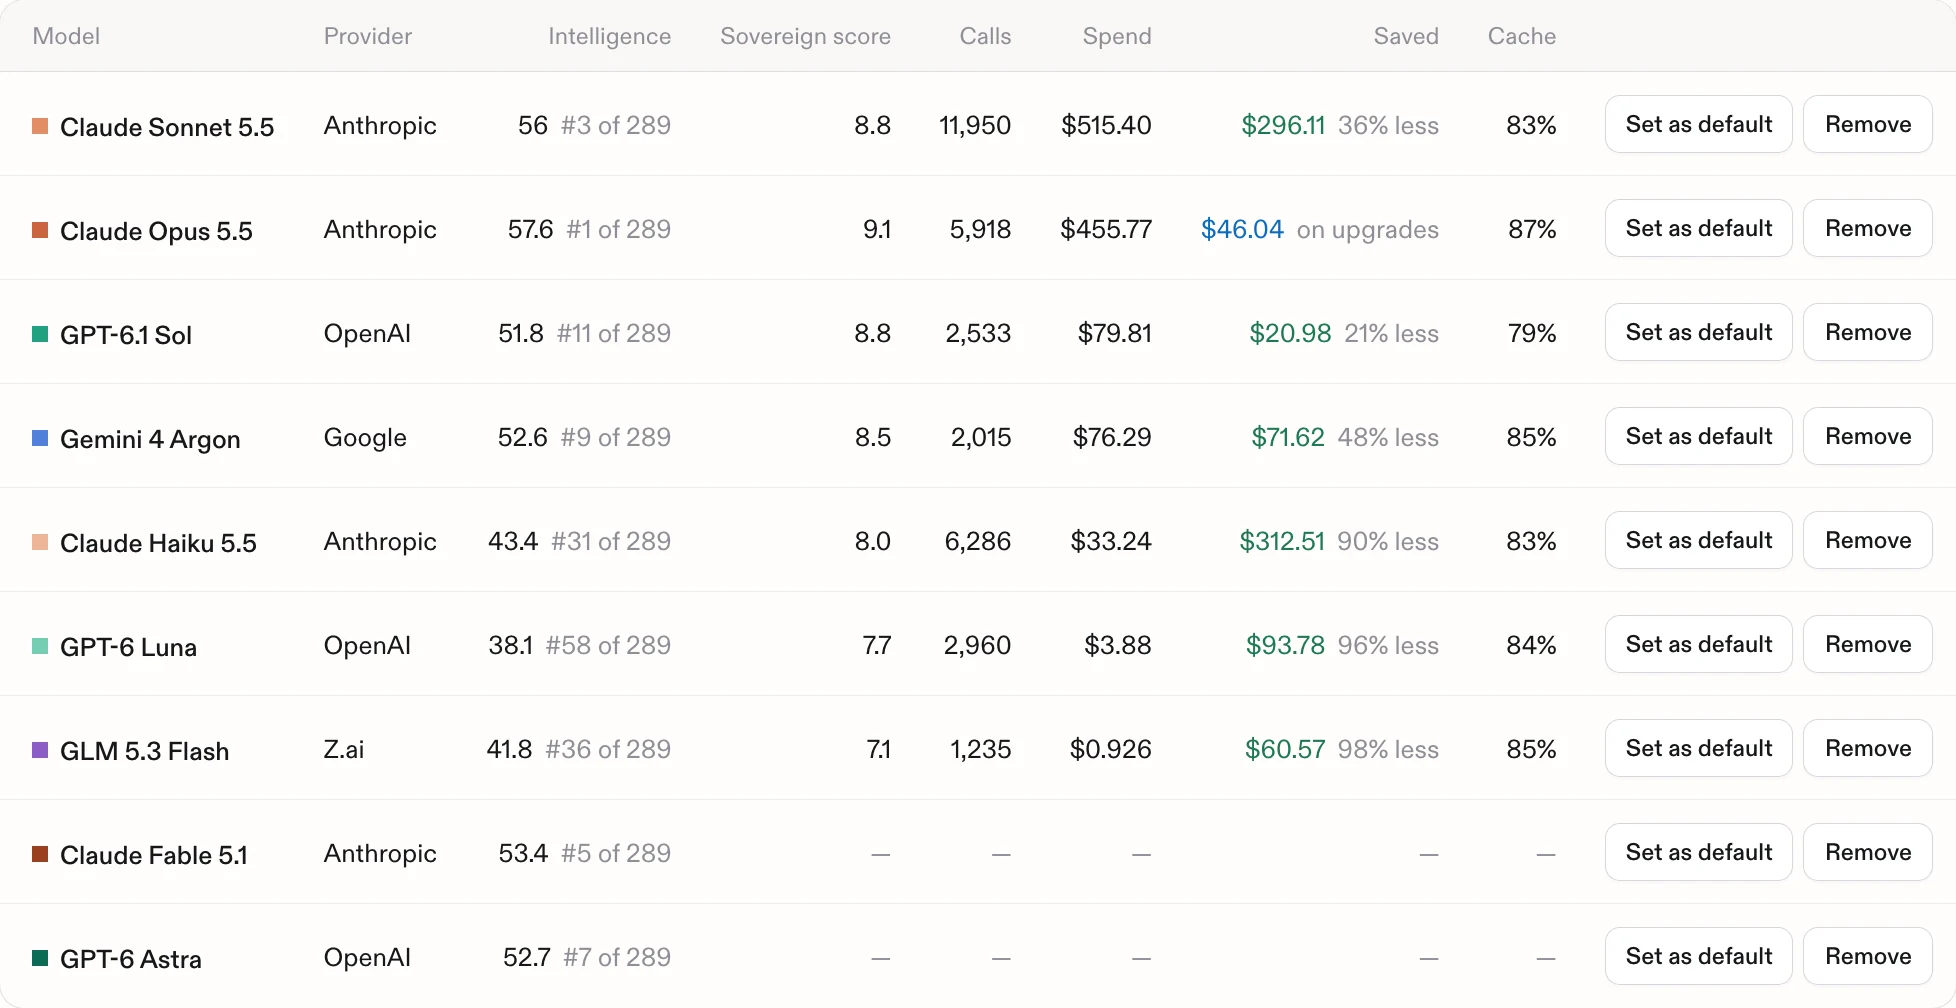
Each request goes to the model that does the work as well for less, and to a stronger one when the work needs it. Conversations stay with one provider, so caches keep paying off.
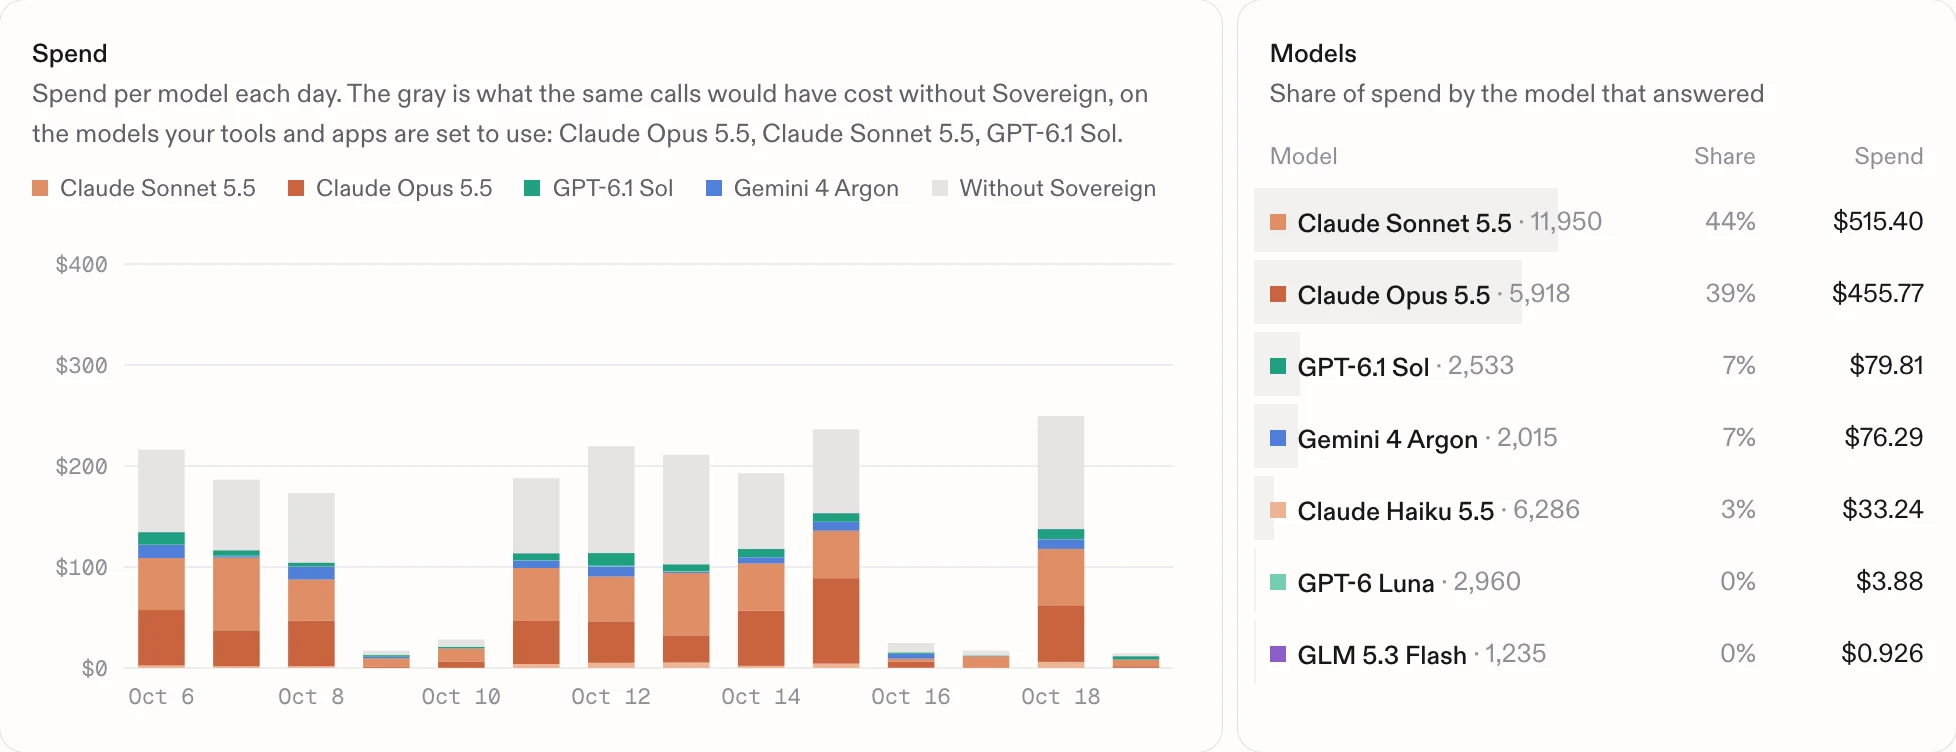
Every call is priced against the model it asked for. The gray is what the same calls would have cost without Sovereign.
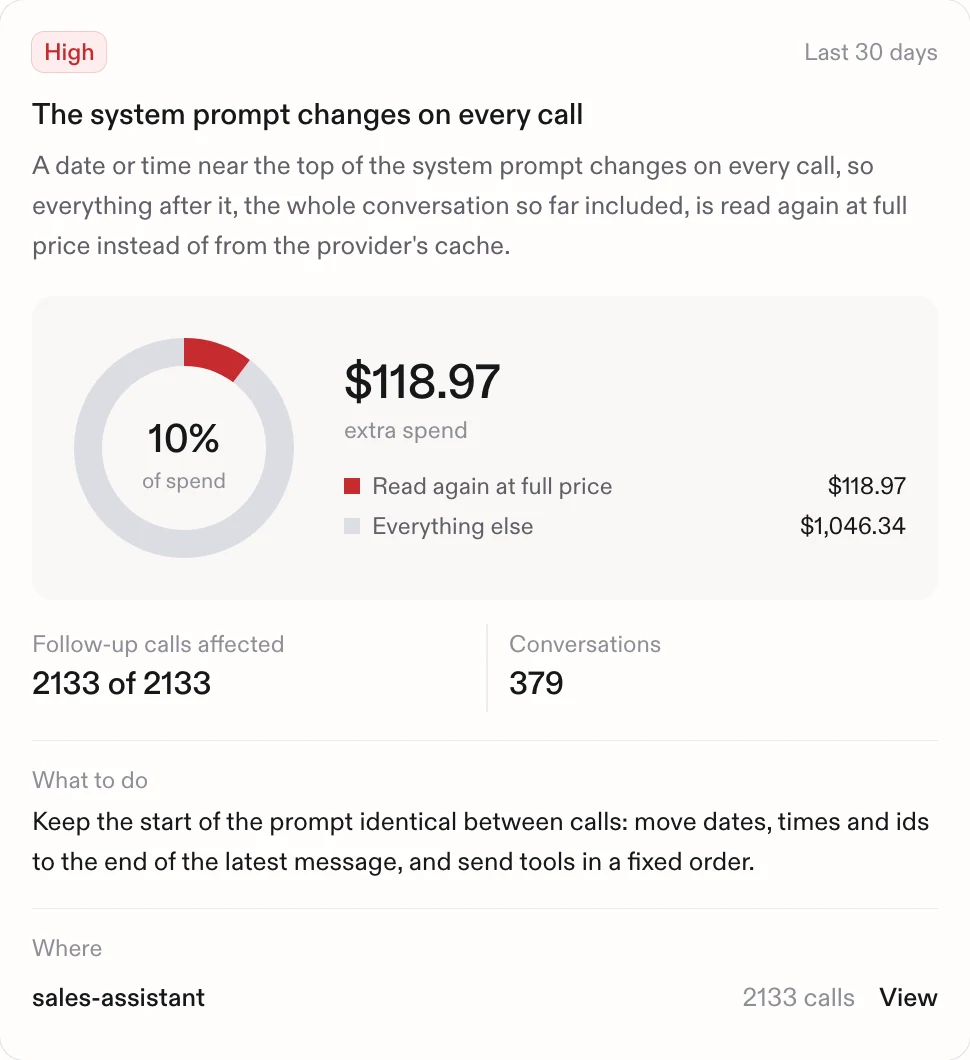
A finding appears only when a change on your side saves real money, with the fix and where it happens.
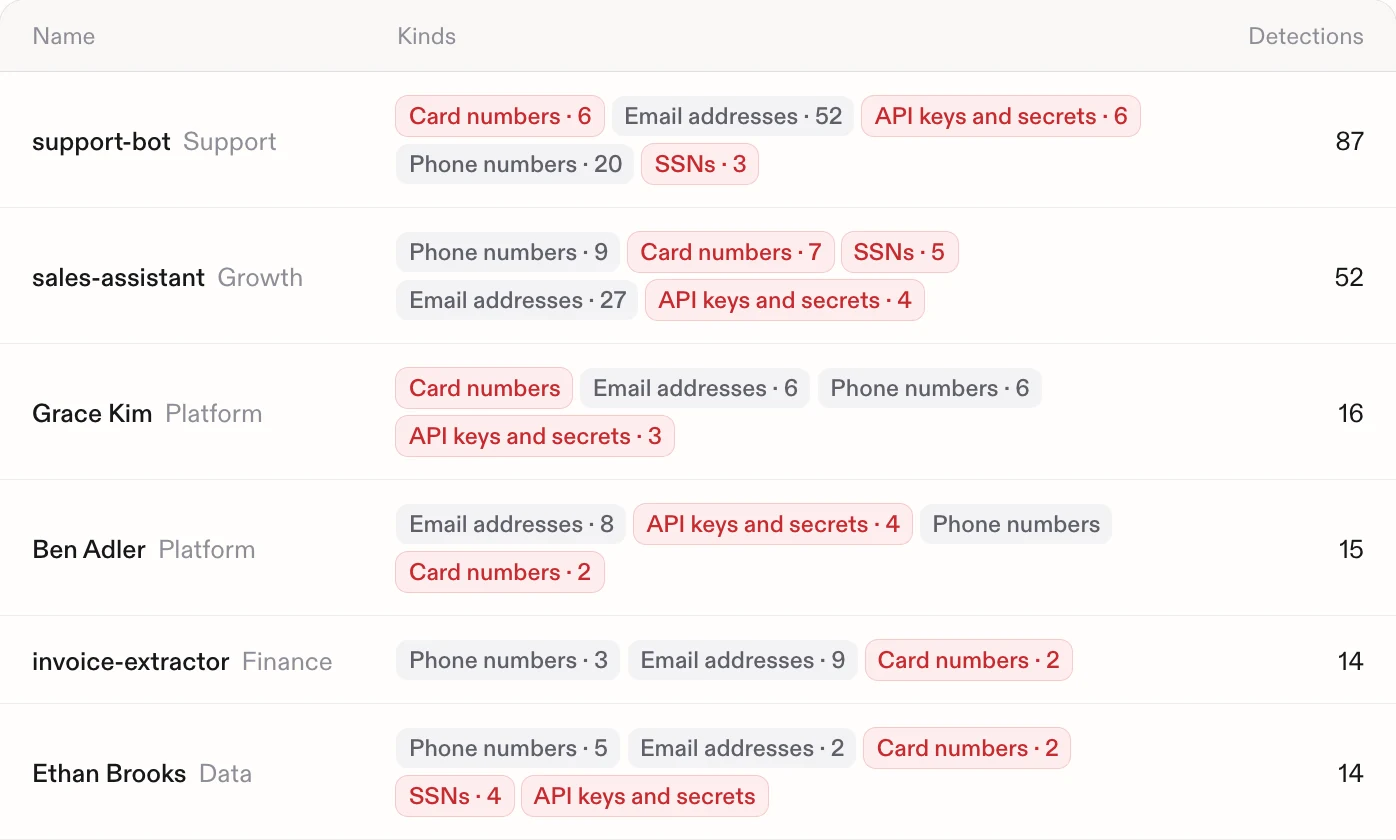
Secrets, card numbers, SSNs, emails and phone numbers are found in every request and masked before anything is stored.
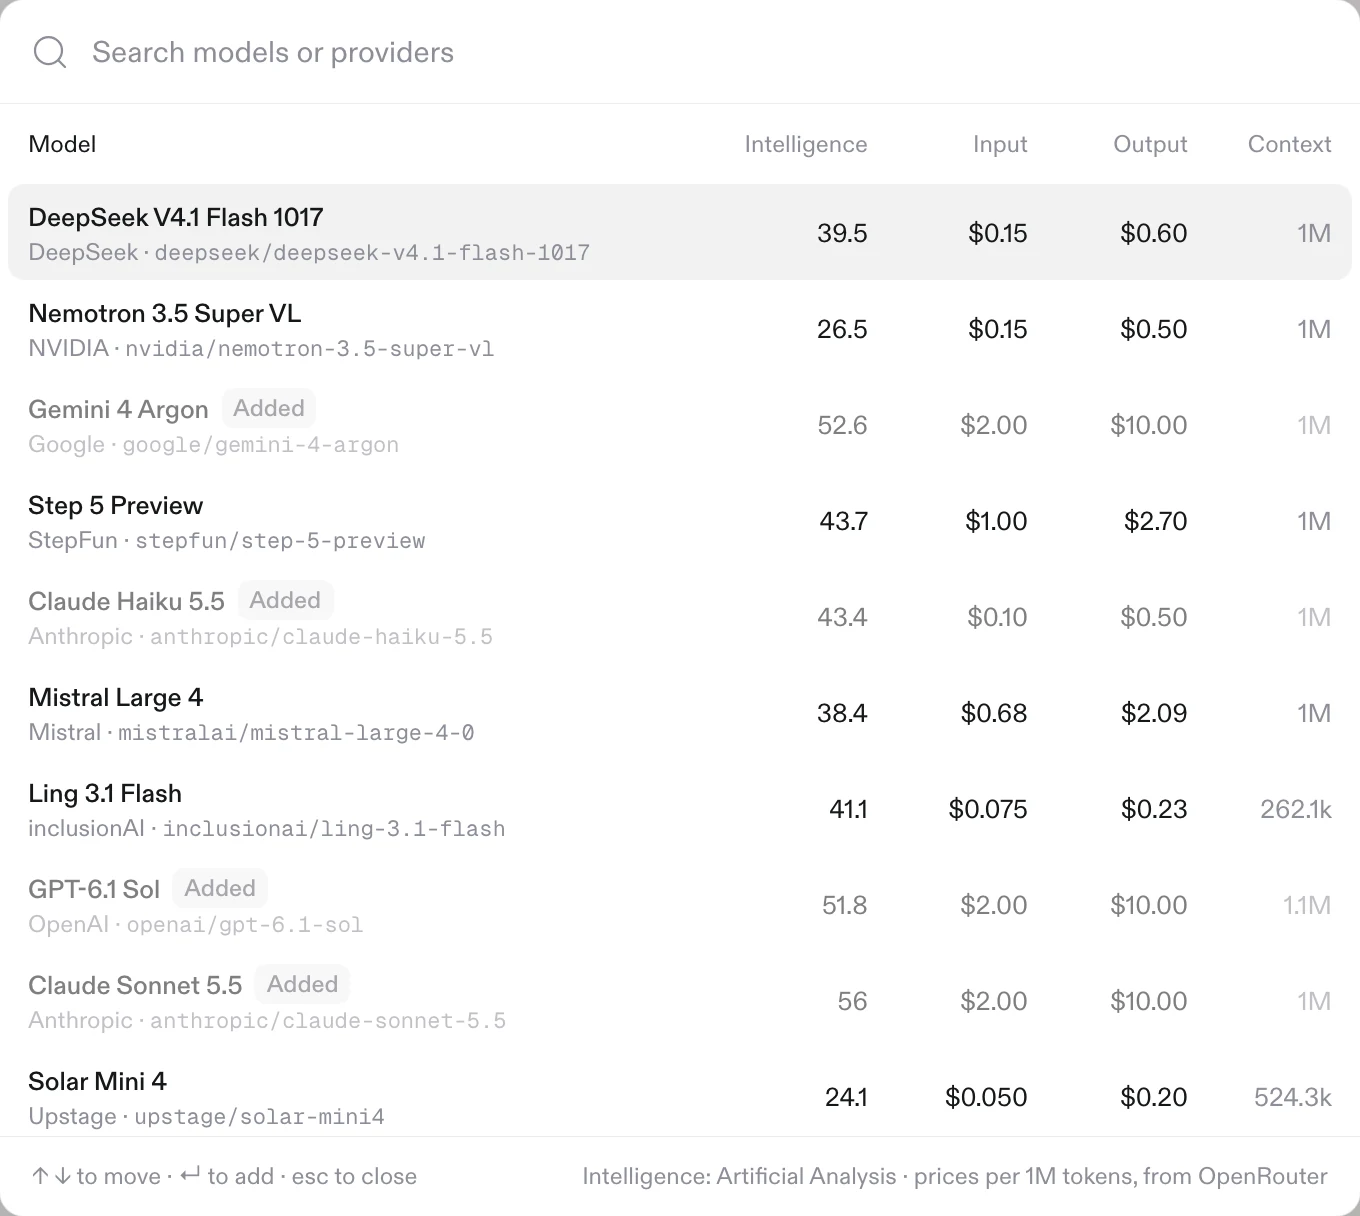
Add models with their prices and benchmark scores, set a default for the company, and remove what you don't use.
How Sovereign learns
A purpose-built decision model reads each request in context and chooses across every model you can use, in a fraction of a second.
Sovereign measures every model on your own traffic, and keeps learning as models improve and your prompts change.
A new model gets its fair share of real work, never above your default's price, until Sovereign knows where it shines.
Benchmark
We sent 320 tasks from four public benchmarks through Sovereign the way Claude Code sends them, asking for Claude Opus 5.5 every time, and checked each answer against the dataset's own answer key or unit tests. The same tasks went straight to Opus, and to Haiku, at the same time.
Claude Opus 5.590%
Sovereign86%
Claude Haiku 5.581%
Claude Opus 5.598%
Sovereign97%
Claude Haiku 5.598%
Claude Opus 5.598%
Sovereign93%
Claude Haiku 5.590%
Claude Opus 5.5100%
Sovereign100%
Claude Haiku 5.5100%
Run on October 21, 2026 through OpenRouter, every request streamed. Costs at list prices, reasoning included. First words arrive 43% sooner with Sovereign. How we measured
| Sovereign | OpenRouter | Not Diamond | LiteLLM | Portkey | |
|---|---|---|---|---|---|
| Smart routing | Yes | Yes | Yes | Yes | Partly1 |
| Learns your work | Yes | No | Partly2 | Partly3 | No |
| Verified savings | Yes | No | Partly4 | Partly5 | No |
| Automatic use cases | Yes | Partly6 | Partly7 | Partly8 | Partly8 |
| Leadership report | Yes | No | No | No | No |
| Non-blocking budgets | Yes | No | No | Partly9 | No |
| Claude Code and Codex | Yes | Yes | Partly10 | Yes | Yes |
| Zero markup | Yes | Partly11 | Partly12 | Yes | Yes |
YesPartlyNot in its documentation
Checked against each product's public documentation on October 21, 2026.
The month on one page: where AI money goes, how much of the work is about your business, and which teams get the most from it, each compared fairly on the same kinds of work. Save it as a PDF and send it.
What your people and apps use AI for, by day, kind of work and person, read from the requests themselves.
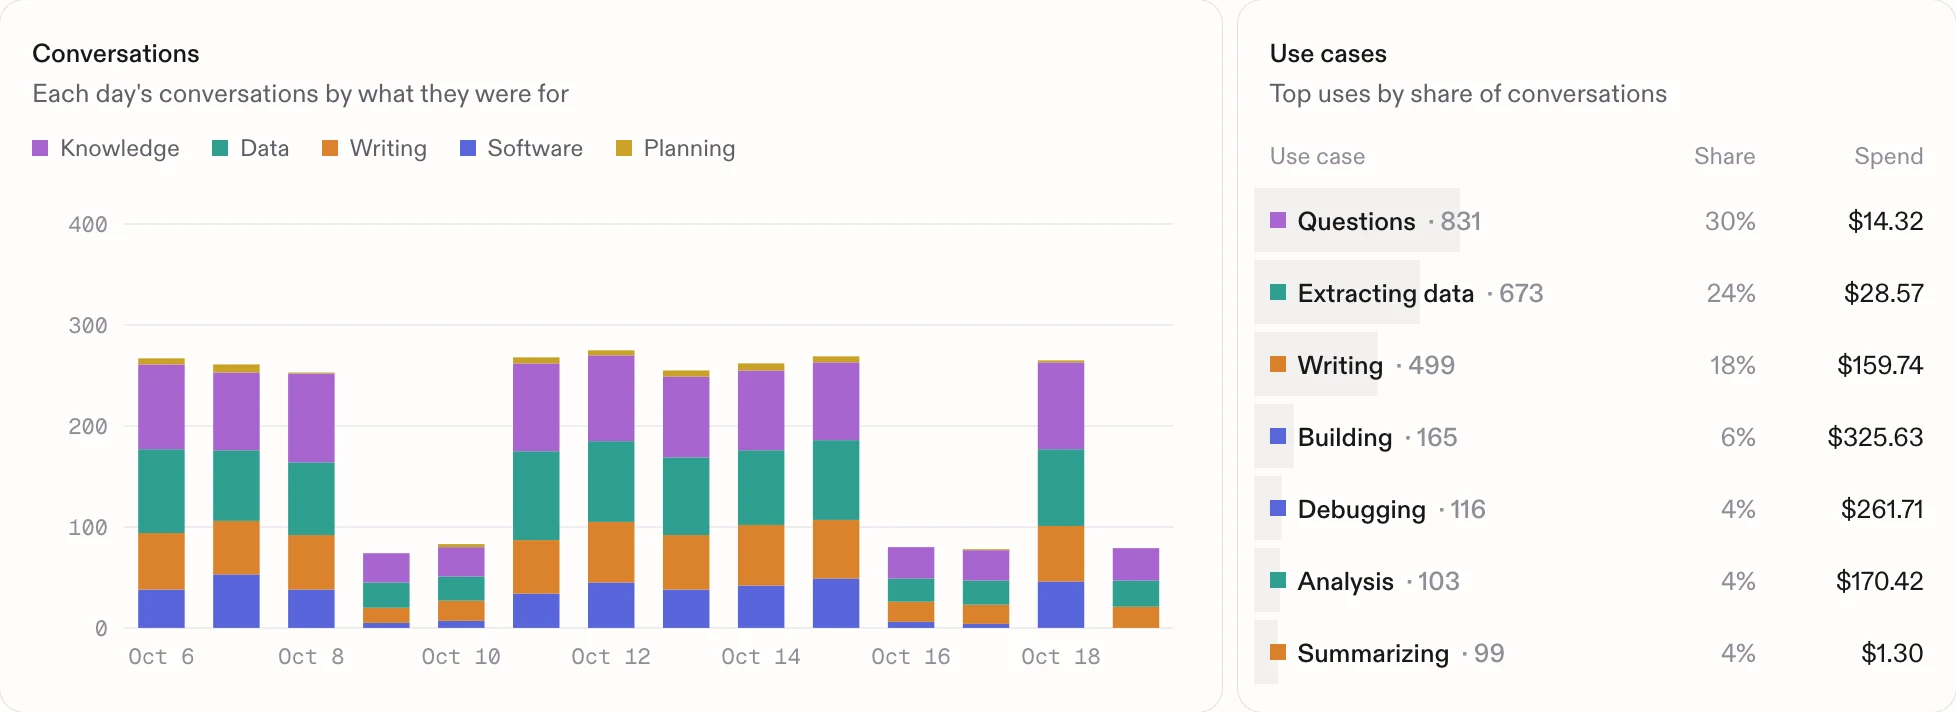
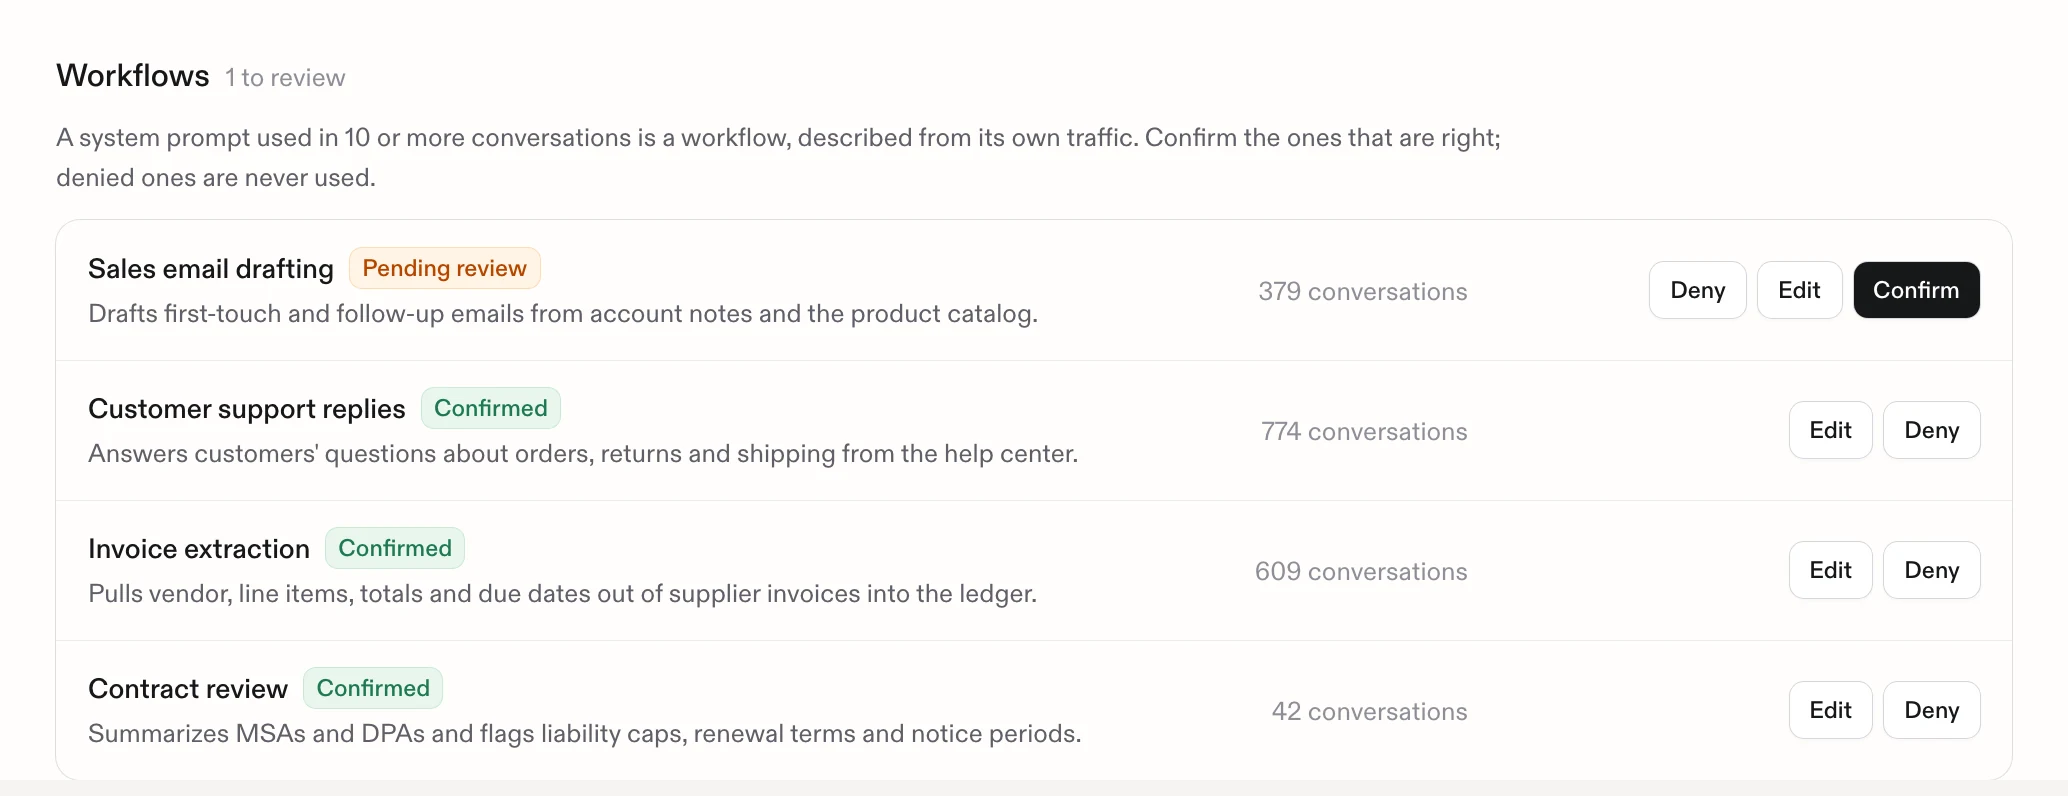
Repeated work, like a support bot or contract review, becomes a named workflow. Confirm it, rename it or turn it off.
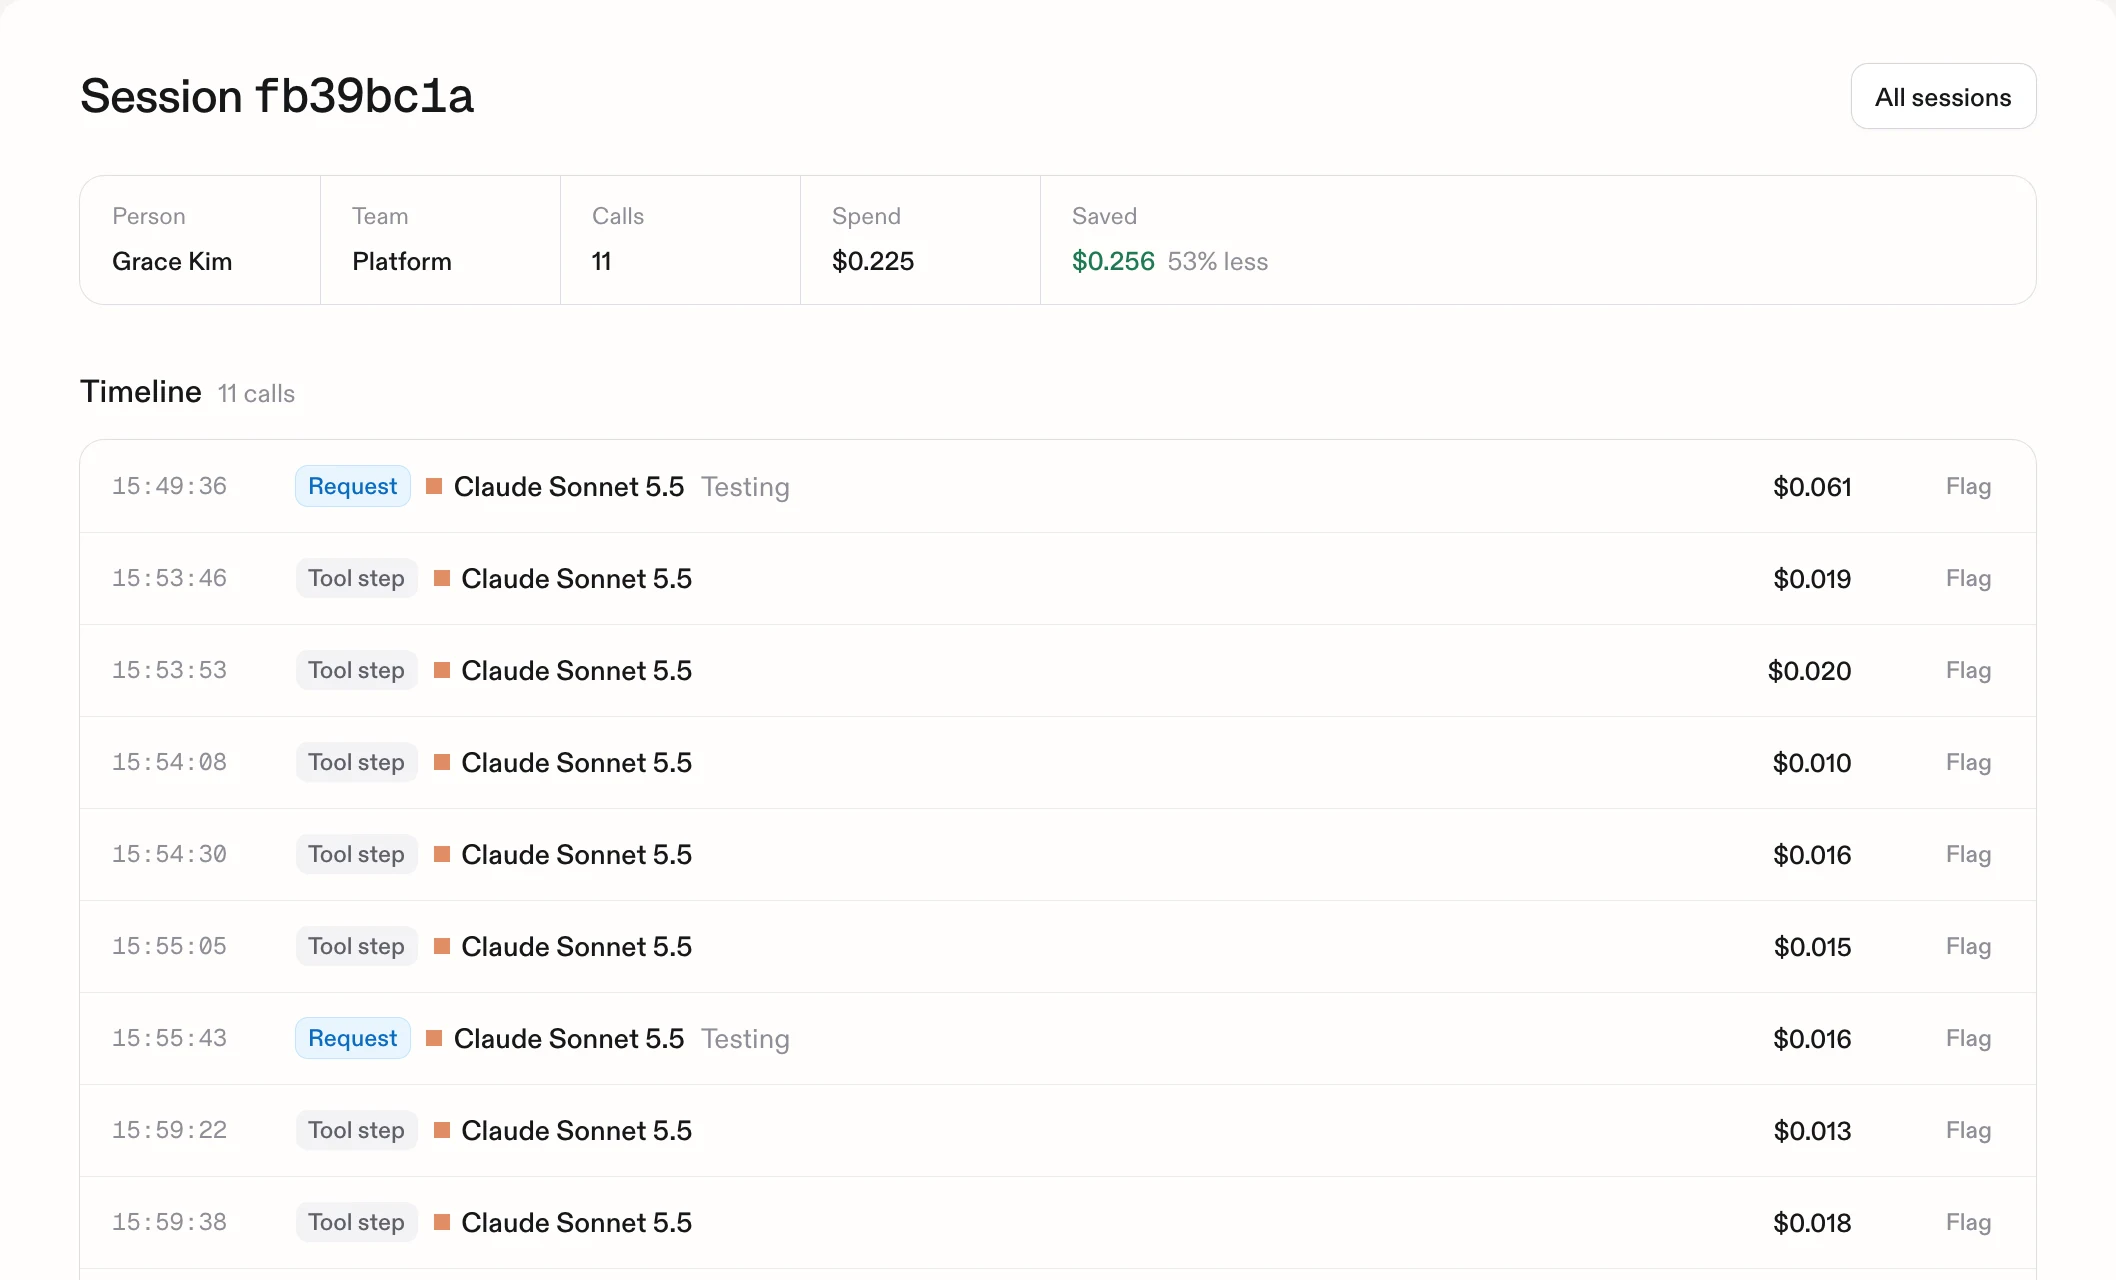
Every conversation: who had it, which model answered each step and what it saved. Prompts and replies stay out of view.
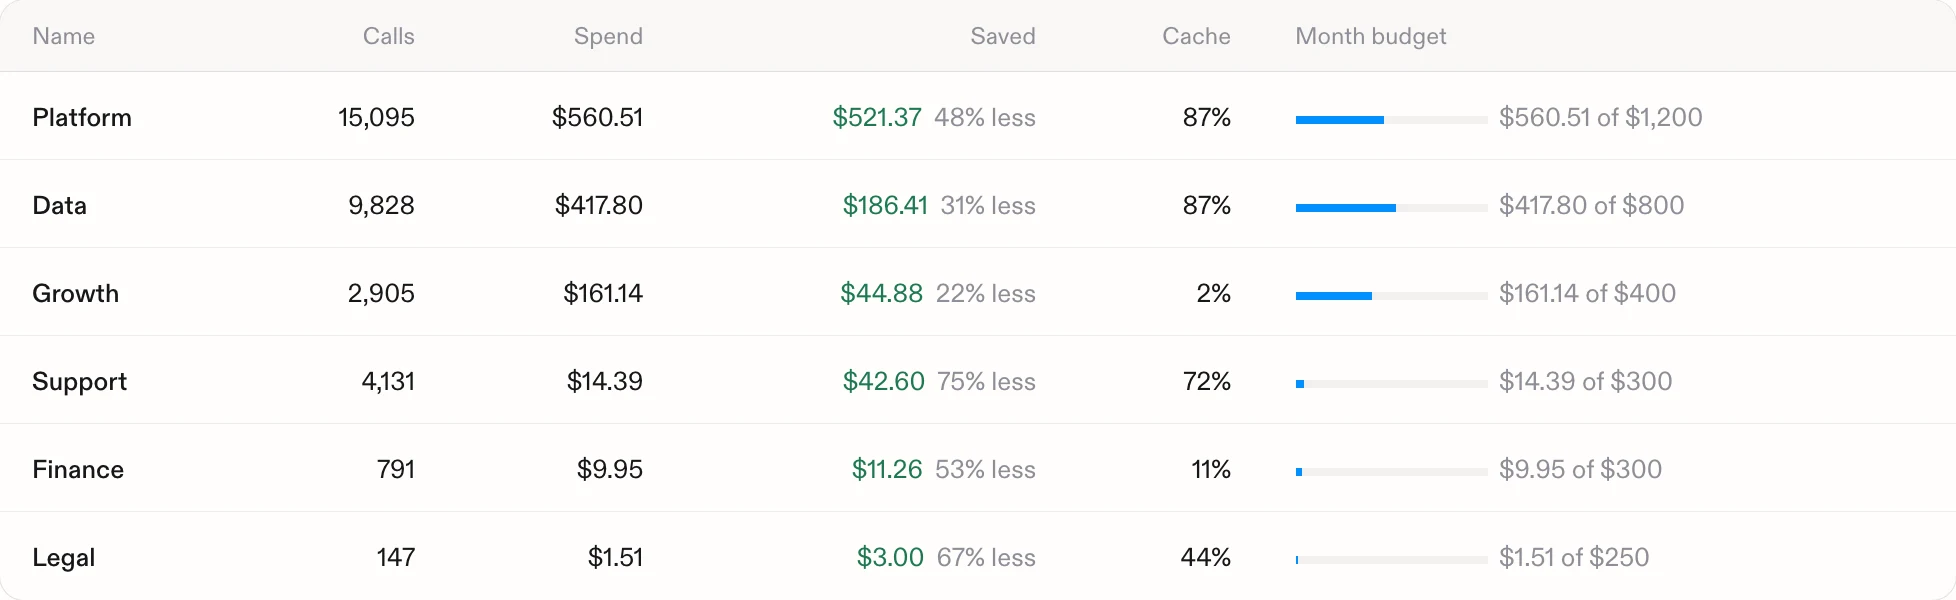
Spend, savings and cache use for every team, with monthly budgets tracked as the month goes.
Add people, apps and teams in the dashboard. Each gets a key of its own.
Point Claude Code, the Anthropic and OpenAI SDKs, or any compatible client at Sovereign.
Requests go to the right model from the first call. Nothing else in your code changes.
# in your shell profile
export ANTHROPIC_BASE_URL=https://sov.solibra.ai
export ANTHROPIC_AUTH_TOKEN=sov_live_…

# then work as usual
claudefrom openai import OpenAI
client = OpenAI(
base_url="https://sov.solibra.ai/v1",
api_key="sov_live_…",
)People and apps hold Sovereign keys. The gateway holds the provider keys, checks every request on the way through and records what it cost.